Decentralized software architecture has moved beyond experimental deployment into a phase characterized by modularity, verifiable computation, and distributed data systems. Engineering teams evaluating protocols, networks, and decentralized middleware face a landscape defined by divergent consensus models, disparate execution layers, and complex integration pathways. Selecting an appropriate protocol stack demands an objective methodology that prioritizes technical soundness, cryptographic security, deterministic finality, and lifecycle operational overhead over market speculation.
Developing a robust deployment requires dissecting the foundational architecture of decentralized systems, detailing their primary capabilities, examining practical deployment methods, and measuring structural constraints. A thorough framework enables architects and systems engineers to assess protocol durability and technical compatibility before committing operational capital.
—
Technical Architecture of Modern Protocol Stacks
The structural composition of decentralized infrastructure has transitioned from monolithic network topologies to decoupled, specialized layers. In a monolithic architecture, consensus, settlement, execution, and data availability occur within a single shared state environment. While this design minimizes coordination complexity, it introduces computational bottlenecks as network verification requirements scale.
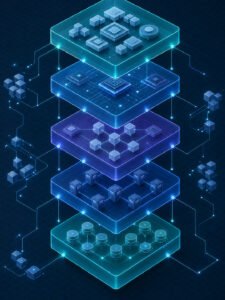
Modern decentralized networks increasingly decouple these responsibilities into discrete, purpose-built components:
+-------------------------------------------------------------+
|                      Application Layer                      |
|           (Decentralized Apps, User Interfaces, SDKs)       |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|                       Execution Layer                       |
|       (Virtual Machines, State Transition Functions, ZKVMs) |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|                      Settlement Layer                       |
|           (Proof Verification, Dispute Resolution)          |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|                    Consensus & Ordering                     |
|           (Proof of Stake, BFT, Leaderless Consensus)       |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|                   Data Availability Layer                   |
|         (Erasure Coding, Data Availability Sampling)        |
+-------------------------------------------------------------+
The Execution Environment
The execution layer executes state transitions, processes transactions, and maintains the global state machine. Historical frameworks rely heavily on stack-based bytecode interpreters operating under gas-metered execution models. While these virtual machines offer broad compatibility with existing smart contracts, modern implementations often incorporate alternative runtimes.
WebAssembly (Wasm) and register-based architectures allow developers to write state-transition logic in standard systems languages like Rust, C++, and Go. Furthermore, the advent of zero-knowledge virtual machines (zkVMs) introduces verifiable computation: state transitions are computed off-chain, generating succinct cryptographic proofs verified by on-chain contracts. This dramatically reduces on-chain computational overhead while preserving deterministic execution guarantees.
Consensus and State Ordering
Consensus mechanisms establish canonical transaction ordering across distributed nodes. Modern networks primarily utilize variations of Proof-of-Stake (PoS) combined with classical Byzantine Fault Tolerant (BFT) voting engines. These designs prioritize deterministic, single-slot finality over probabilistic settlement, preventing deep chain reorganizations.
Alternative consensus models leverage Directed Acyclic Graphs (DAG) to decouple transaction dissemination from metadata ordering. Under a DAG-based paradigm, transactions are validated concurrently across a network of parallel processing paths, achieving high transaction throughput without sacrificing asynchronous safety guarantees.
Data Availability and Cryptographic Verification
A primary vulnerability in scaling execution systems is data withholding. If an execution node processes a transaction batch but suppresses the underlying transaction data, other network participants cannot verify state changes or construct withdrawal proofs.
Dedicated data availability layers solve this by decoupling bulk payload storage from consensus. Using erasure coding and Data Availability Sampling (DAS), light nodes verify that complete block data has been published to the network by downloading tiny, randomly sampled mathematical fragments. Cryptographic polynomial commitments—such as Kate-Zaverucha-Goldberg (KZG) commitments—further guarantee that published data corresponds directly to the commitments embedded within state headers.
—
Core Capabilities and Evaluation Criteria
When assessing modern protocols, engineering organizations must establish quantifiable evaluation vectors. Relying on broad throughput metrics like theoretical transactions per second often masks critical constraints, such as state-growth limits, compute-heavy execution costs, and communication bottlenecks.
| Evaluation Vector | Key Technical Metrics | Operational Significance |
|---|---|---|
| Deterministic Finality | Time-to-finality (seconds/slots), reorganization depth | Dictates settlement latency and systemic financial risk |
| State Footprint & Pruning | Growth rate (GB/month), light-client proof sizes | Determines long-term full-node validation sustainability |
| Execution Throughput | Gas per second, parallelization conflict rates | Measures practical computation capacity under real-world loads |
| Cryptographic Resilience | Primitive age, proof verification costs, setup assumptions | Influences long-term protocol security and trust surfaces |
| Decentralization Topology | Nakamoto coefficient, physical geographic distribution | Quantifies vulnerability to infrastructure-level censorship |
Quantifying Cryptographic Safety Assumptions
Evaluating decentralized protocols requires examining the cryptographic primitives underlying their security models. Trusted setups, common in certain zero-knowledge proof constructions, require verified ceremonies to ensure toxic waste parameters are destroyed. Conversely, systems employing transparent setups eliminate this multi-party operational risk at the cost of larger proof sizes and higher verification overhead.
Teams must also audit signature schemes and hash functions. While traditional elliptic curve cryptography remains the standard for account validation, protocols increasingly support account abstraction natively. This capability permits alternative signature validation algorithms, enabling hardware-level enclave integration, session keys, and programmable access controls directly inside smart contract state.
Node Economics and Validation Requirements
The decentralization of a network is bound to the physical hardware constraints required to operate a full validating node. When the computational, memory, or bandwidth requirements to verify the chain state exceed commodity server specifications, node operation inevitably centralizes into specialized data centers.
Technical reviews must calculate the unpruned state growth per million transactions. Protocols that implement native state-expiry mechanisms or incentivize distributed state rent prevent unconstrained storage growth. Without these mechanisms, the long-term operational cost of maintaining archive and validation nodes compounds exponentially, degrading network resilience.
—
Target Application Scenarios and Workload Profiles
Different decentralized workloads place contrasting demands on the underlying protocol layers. Selecting an architecture requires mapping the structural properties of the application to the operational strengths of the network.
High-Frequency State Verification
Applications handling frequent micro-transactions, decentralized order books, and real-time gaming infrastructure demand sub-second latency and minimal execution fees. Monolithic architectures utilizing parallelized transaction execution runtimes excel in these environments.
By executing independent transactions concurrently across multiple processor threads—detecting access conflicts dynamically via software transactional memory or access lists—these networks achieve the raw computational density necessary for high-frequency state updates. However, these systems often require higher-grade hardware for full-node validators.
Institutional Asset Settlement and Verifiable Logic
Enterprise workflows, tokenized debt facilities, and multi-jurisdictional settlements prioritize deterministic security, predictable operational costs, and absolute data availability over ultra-low execution latency. For these use cases, specialized zero-knowledge rollups or dedicated application-specific chains (app-chains) provide isolated execution spaces.
Operating an app-chain isolates an enterprise from network congestion caused by unrelated third-party applications, providing predictable fees and dedicated block space. Furthermore, zero-knowledge proofs enable institutions to demonstrate compliance, solvency, or regulatory checks without exposing proprietary transaction balances or business logic to public ledgers.
Distributed Data Orchestration and Storage
Not all application states belong directly on ledger state machines. Projects requiring content-addressable storage, verifiable off-chain databases, or oracle data delivery pipelines depend on hybrid decentralized systems.
Here, the blockchain functions purely as a dispute-arbitration and settlement layer, while distributed file systems or compute-over-data networks handle storage and computation off-chain. Cryptographic storage proofs verify that data providers maintain redundant, uncorrupted replicas of assigned datasets over time.
—
Integration Pipelines and Deployment Methodology
Deploying applications onto decentralized infrastructure requires tooling, environmental configurations, and continuous deployment pipelines that differ significantly from standard cloud-native environments.
+-------------------------------------------------------------+
|                 1. Local Emulation Environment              |
|        (In-Memory Node, Mock Consensus, Ephemeral State)     |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|                   2. Deterministic Testing                  |
|     (Static Analysis, Invariant Fuzzing, Formal Validation) |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|                 3. Staging and Testnet Phase                |
|      (Multi-Node Testnet, Faucet Orchestration, Gas Profil) |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|              4. Production On-Chain Deployment              |
|      (Deterministic Factory Deployment, Upgradable Proxies) |
+-------------------------------------------------------------+
|
+-------------------------------------------------------------+
|            5. Telemetry & RPC Node Infrastructure           |
|      (Automated Indexers, Private Relays, Fallback RPCs)    |
+-------------------------------------------------------------+
Development Environments and Local Emulation
Reliable development begins with deterministic local emulation. Engineering teams run headless, local instances of the targeted virtual machine with exposed JSON-RPC interfaces. These local environments must feature:
- Instantaneous State Reset: Ability to snapshot, revert, and seed network states programmatically within integration test suites.
- Account Impersonation: Native tooling capabilities to bypass cryptographic signatures locally, allowing developers to execute test scenarios using arbitrary contract states or administrator balances.
- Trace and Debug Callbacks: Granular opcode-level execution tracing to diagnose gas exhaustion faults, reentrancy vulnerabilities, and unexpected revert conditions.
Testnet Validation and Invariant Fuzzing
Before deploying contracts to a production environment, verification must extend beyond unit testing to include property-based testing and invariant fuzzing. Developers define core assertions—such as balance conservation or authorization invariants—and automated fuzzing engines generate millions of randomized inputs to identify edge cases that compromise the logic.
Target Function Calls ---> [ Fuzz Engine: Random Inputs ] ---> State Transition
|
v
[ Invariant Assertion Checks ]
- Total balances match
- Unauthorized access reverts
- Math operations do not overflow
Following static validation and fuzzing, applications migrate to public testnets. Testnet deployments mirror production configurations, exposing smart contracts to actual latency, decentralized RPC endpoint dynamics, and multi-node transaction ordering anomalies.
Remote Procedure Call (RPC) Reliability and Key Management
Production systems interact with decentralized networks through RPC layers. A common vulnerability is reliance on single, unauthenticated public RPC providers. Public endpoints enforce aggressive rate limits, introduce single points of failure, and leak transaction metadata to network intermediaries.
Production infrastructure mandates private RPC provider clusters deployed behind load-balancing reverse proxies with automatic failover capabilities. For operations requiring automated transaction submission (e.g., automated market making, settlement, rebalancing), private relays protect unconfirmed transactions from predatory front-running and maximal extractable value (MEV) exploits.
For critical key management, automated transaction submission pipelines must never store raw private keys in environment files or plaintext disks. Production keys belong in hardware security modules (HSMs) or cloud-native key management services supporting threshold signing schemes (TSS), enforcing multi-party cryptographic authorization before broadcasting transactions.
—
Inherent Strengths and Systemic Constraints
Architects must weigh the immutable benefits of decentralized state machines against their architectural liabilities. Deploying workloads to decentralized protocols introduces trade-offs fundamentally distinct from traditional distributed systems.
Inherent Strengths
The primary benefit of decentralized architecture is trust-minimized determinism. Once verified and recorded on a finalized block, data and state-transition logic cannot be unilaterally altered, rolled back, or deleted by a centralized host. This characteristic guarantees continuous uptime and platform neutrality.
Additionally, composability enables disparate software protocols to interoperate permissionlessly within a unified state environment. Contracts deployed by different organizations can read from, call, and build upon each other in a single atomic transaction without requiring private APIs, bilateral integrations, or formal coordination agreements.
Systemic Constraints
These operational advantages come with fundamental trade-offs:
- Latency and Finality Delays: Unlike centralized relational databases that process transactions in single-digit milliseconds, decentralized networks require cross-node gossip propagation and consensus voting. Even high-performance networks exhibit settlement latencies that are orders of magnitude slower than centralized counterparts.
- Deterministic Immutability Overhead: While immutability protects against unauthorized modification, it complicates incident response and software patching. Bugs deployed to non-upgradable smart contracts are permanent. Remediating vulnerabilities requires complex proxy configurations, migration pathways, or multi-signature consensus coordination, each introducing technical governance risks.
- State Bloat and Storage Inefficiencies: Storing unstructured data directly in decentralized state machines is cost-prohibitive. Every byte stored on-chain must be replicated, verified, and held in memory or high-speed storage by every validating full node across the globe indefinitely.
- Economic Attack Vectors: Systems rely on economic game theory for operational integrity. If the cost to corrupt a consensus layer or manipulate an external data oracle drops below the potential value that can be extracted from connected applications, the protocol becomes vulnerable to economic exploits regardless of its cryptographic correctness.
—
Strategic Selection Framework
To systematically choose between available protocol layers, software architects can utilize a sequential decision-making process based on workload attributes:
[ Application Workload Analysis ]
|
v
High Storage / File Payloads? -------------------> Use Off-Chain Cryptographic Storage
|                                      (Blockchain for hashes/roots only)
No
|
v
High Frequency / Low Latency Operations? --------> Evaluate Parallel VM / High-Throughput Chains
|
No
|
v
Custom Governance / Regulatory Needs? -----------> Deploy Dedicated App-Chain or L3
|
No
|
v
General Logic / Maximum Liquidity Access --------> Standard EVM/Wasm Execution Layer
Step 1: Workload Decoupling and State Classification
Analyze data flows to separate state transitions into on-chain components and off-chain computational tasks.
- Off-chain: Complex relational queries, machine learning inferences, static media, and private business logic belong in traditional compute or verifiable off-chain frameworks.
- On-chain: Core custody, financial logic, ownership mappings, and final dispute settlement belong directly on-chain.
Step 2: Selecting the Execution Runtime
Examine whether standard virtual machine environments meet security and performance goals. If legacy tooling, extensive third-party library access, and security auditing ecosystems are paramount, choose established bytecode standards. If the application relies on compute-intensive cryptography, formal verification, or native multithreading, choose modern runtimes such as Wasm or zkVM-compatible architectures.
Step 3: Determining the Layer Topology
Select whether the deployment belongs on a shared execution network, an existing layer-2 rollup, or a sovereign application-specific chain:
- Shared Layer-1 Networks: Recommended when deep composability with external protocols and immediate access to existing state liquidity are the primary technical drivers.
- Layer-2 Rollup Environments: Ideal for teams that require the settlement security guarantees of a major base chain but need lower transaction overhead and higher execution throughput.
- Application-Specific Chains (App-chains): Appropriate for applications with dedicated computational demands, unique state transition requirements, or specialized compliance and fee-tokenomics rules that cannot share state with noisy neighbor applications.
Step 4: Tooling Ecosystem and Operational Auditing
Assess the maturity of developer ecosystems. A protocol with theoretically superior technical specs is an operational risk if it lacks:
- Mature, actively maintained local client libraries and test frameworks.
- Multiple independent, production-ready RPC node providers.
- Comprehensive hardware wallet and institutional custody integration.
- Independent, specialized security audit firms with deep domain expertise in the target environment’s specific runtime bugs.
Choosing the proper protocol layer is an engineering exercise in managing trade-offs. Successful implementations prioritize verifiable security models, manageable node operational overhead, and deterministic execution environments that align directly with application-specific throughput and trust requirements.